Phase 1: Initial GPU Compute Node
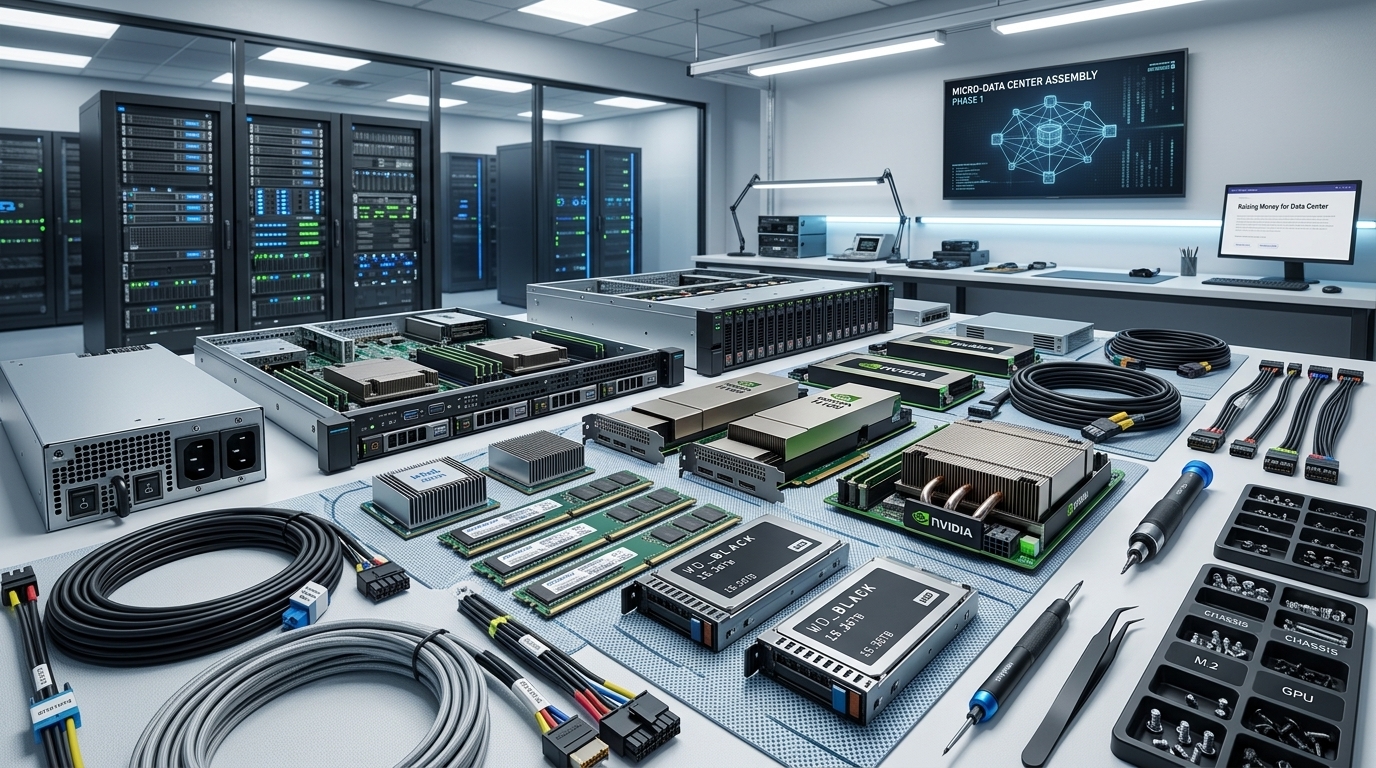
This project funds the primary hardware component under the Micro Data Center Campaign: our first dedicated high-density GPU compute node. This single bare-metal server serves as the computational engine required to begin pre-training, fine-tuning, and evaluating the proprietary ML models powering our fundraising platform. Funds collected here directly purchase enterprise GPUs, server motherboards, high-frequency RAM, and specialized server enclosure hardware.
Added straight to your donation basket
Phase 1: Initial GPU Compute Node
This project funds the primary hardware component under the Micro Data Center Campaign: our first dedicated high-density GPU compute node. This single bare-metal server serves as the computational engine required to begin pre-training, fine-tuning, and evaluating the proprietary ML models powering our fundraising platform. Funds collected here directly purchase enterprise GPUs, server motherboards, high-frequency RAM, and specialized server enclosure hardware.
Artificial Intelligence and Data Science
Organizer
Tech Ventures
Project Objective: Core Compute Acceleration
Under our overarching Micro Data Center initiative, this specific project finances the core engine of the entire cluster: the Initial GPU Compute Node. Without dedicated acceleration silicon, training and testing our fundraising optimization models in-house is impossible.
Instead of paying recurring, non-equity rental costs to third-party cloud providers, this project secures physical ownership of our initial training pipeline hardware.
Specific Hardware Funded by This Project
Accelerator Hardware: Enterprise-grade GPUs capable of distributed mixed-precision training (FP16/BF16) and transformer fine-tuning.
Host Processing: Dual multi-core server processors to eliminate I/O bottlenecks during batch operations.
System Memory: 256GB+ ECC DDR5 memory to sustain large in-memory dataset handling and parallel data loading.
Storage Backbone: High-endurance NVMe M.2 drives for high-throughput checkpointing and dataset caching.
Deliverables & Implementation Steps
Procurement: Acquire primary accelerator cards, chassis, host processors, and memory modules.
Bench Testing: Run 72-hour thermal stress tests, CUDA memory checks, and power stability baselines.
Cluster Integration: Mount into the central server rack, connect to local network fabric, and configure the training scheduler.
Initial Model Verification: Execute benchmark runs on our platform's recommendation models to verify throughput.
Fundraising on Artificial Intelligence and Data Science takes just a few minutes
Give Happiness
Giving happiness to others is one of the most fulfilling things you can do in life.
Share Love
When you share love with those around you, you create a ripple effect of kindness.
Build Socially
Building socially requires not just connecting with others, but also actively contributing.